Structuring Claude Code with CLAUDE.md: Organizing Complex Rules and Project Data
How to structure complex workflows in Claude Code using CLAUDE.md, modular Markdown files, and separate project data.
Complex tasks are much easier to handle with AI when you do not have to explain the same rules again every time you start a new session. In Claude Code, this is exactly what the CLAUDE.md file is designed for.
I came across this while working on a scheduling problem. The task is not just to find suitable examination dates. For each date, suitable examiners also have to be assigned. This involves availability, exclusion criteria, priorities, workload distribution, and various special cases.
At some point, this becomes too complex for a single prompt.
A structured project setup is a much better approach.
The Central File: CLAUDE.md
Claude Code uses a file called:
CLAUDE.md
It can be placed directly in the project directory:
my-project/
├── CLAUDE.md
└── ...
This file acts as a persistent set of project instructions. It can describe what the project is supposed to achieve, which rules apply, and how Claude should approach the task.
In that sense, CLAUDE.md is something like the constitution of the project.
A basic structure might look like this:
# Examination Scheduling

## Goal

This project is used to:

1. determine suitable examination dates,
2. select suitable examiners for each date,
3. comply with all organizational and subject-specific constraints.

## Workflow

Always perform scheduling in the following order:

1. Validate the input data.
2. Determine possible dates.
3. Apply exclusion criteria.
4. Determine possible examiners for each date.
5. Select examiners according to the prioritization rules.
6. Explicitly report conflicts that cannot be resolved.
7. Validate the final result.

Do not make assumptions about missing information.
Clearly flag ambiguous or contradictory data.
This gives Claude not only the business rules, but also a defined decision-making process.
Do Not Put Everything into a Single File
For larger projects, CLAUDE.md should not turn into a several-hundred-line manual.
A modular structure is easier to maintain:
examination-scheduling/
│
├── CLAUDE.md
│
├── docs/
│   ├── scheduling.md
│   ├── examiner-selection.md
│   └── special-cases.md
│
├── data/
│   ├── dates.csv
│   ├── examiners.csv
│   └── availability.csv
│
└── output/
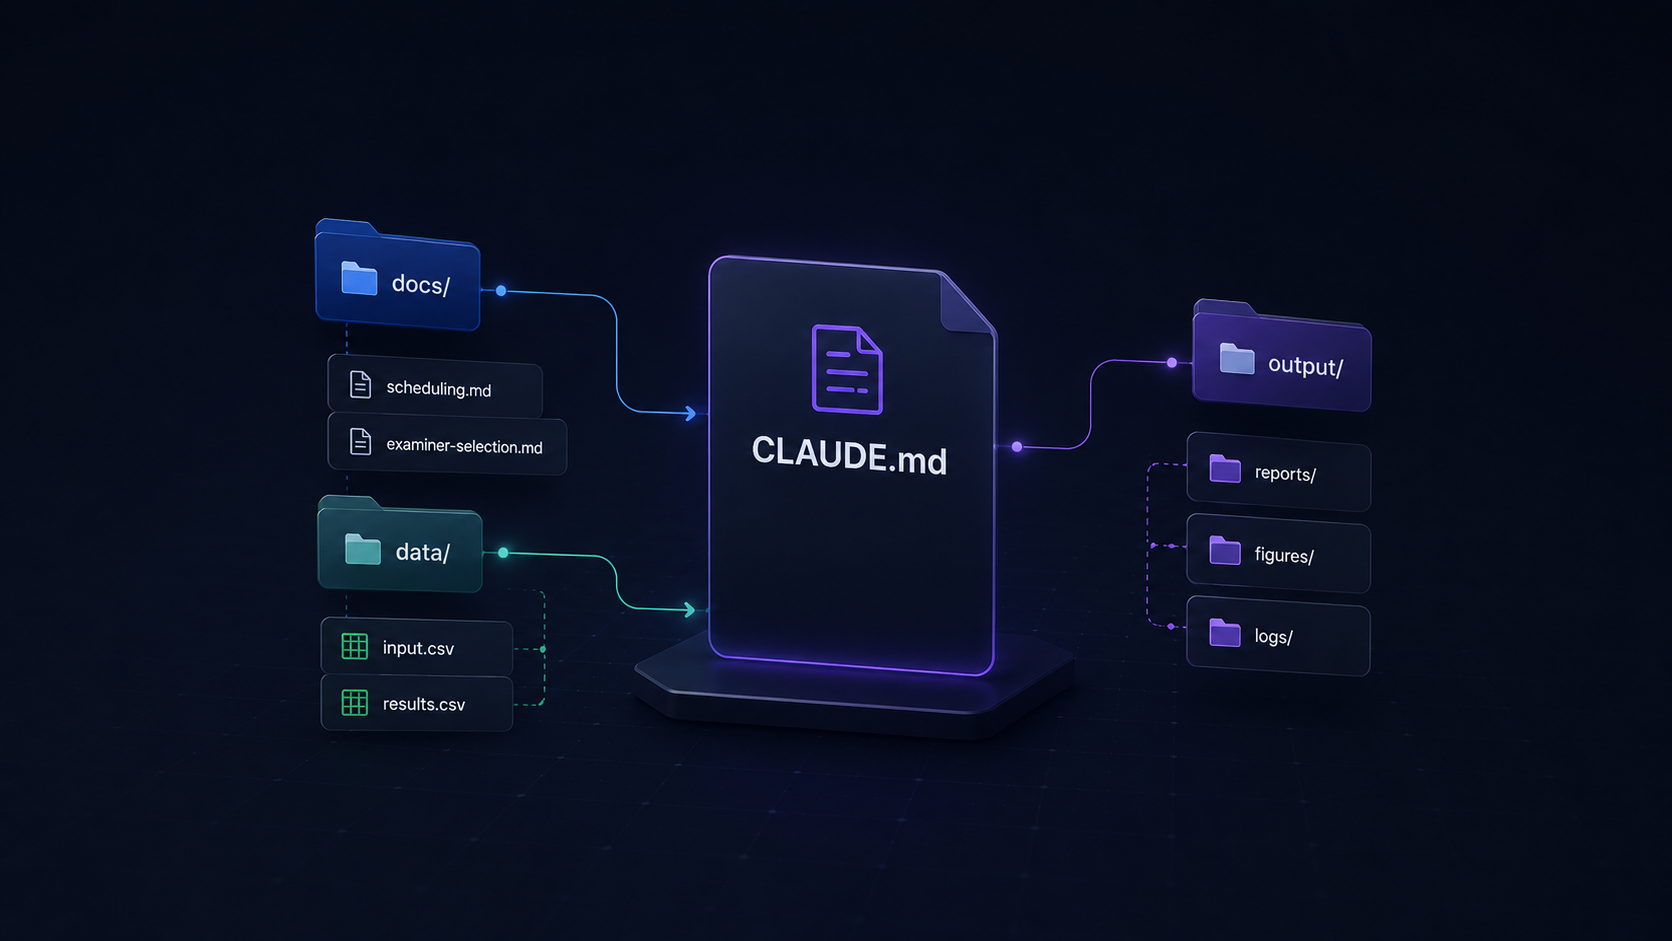
The central CLAUDE.md then contains the overall project framework, while the detailed rules are stored in separate Markdown files.
Including Additional Markdown Files
Claude Code supports references to additional files using the @ syntax.
For example, CLAUDE.md can contain:
## Scheduling Rules

See @docs/scheduling.md

## Examiner Selection Rules

See @docs/examiner-selection.md

## Special Cases

See @docs/special-cases.md
This allows each group of rules to be maintained separately.
The file docs/scheduling.md could look like this:
# Scheduling Rules

## Input Data

For each candidate, consider:

- possible examination periods
- excluded dates
- required lead times

## Hard Constraints

A date must be excluded if ...

## Soft Constraints

If several dates are possible, prefer ...

## Special Cases

If ...
Examiner selection can be handled in another file:
# Examiner Selection Rules

## Requirements

An examiner may be selected if ...

## Exclusion Criteria

An examiner must not be selected if ...

## Prioritization

If several examiners are eligible, use the following order:

1. ...
2. ...
3. ...

## Workload Distribution

...
This separation has an important advantage: individual rule sets can be changed without making the main project file increasingly difficult to understand.
Distinguish Between Hard and Soft Rules
For complex scheduling problems, it is not enough to simply list the rules.
Their priority matters as well.
A section in CLAUDE.md might therefore look like this:
## Rule Priority

If rules conflict, use the following priority:

1. mandatory exclusion criteria
2. availability
3. subject-matter qualification
4. workload distribution
5. preferences

A lower-priority rule must never override a higher-priority rule.
This distinction is particularly important.
A rule such as:
Distribute examinations as evenly as possible among examiners.
is fundamentally different from:
This examiner must not be assigned on this date.
Without explicit priorities, a language model may try to balance both requirements, even though one of them is actually mandatory.
Separate Rules from Data
Another important design decision is the separation between the rule set and the current data.
Rules such as:
There must be at least 30 minutes between two examinations
assigned to the same examiner.
or:
An examiner must not examine candidates from department X.
belong in the Markdown documentation.
Current state, on the other hand, is better stored in structured data files.
For example:
Examiner;Date;Availability
Miller;2026-09-14;available
Smith;2026-09-14;unavailable
Depending on the project, suitable formats include:
- CSV
- JSON
- YAML
- Excel
- databases
The documentation therefore describes how decisions are made.
The data files describe what the decisions are based on.
Keeping these two things separate makes the project much easier to maintain.
Define the Expected Output
Another often-overlooked aspect is the output format.
Claude should not only know how to make a decision. It should also know what the result is expected to contain.
For example:
## Output

The result must include:

- selected date
- selected examiners
- reason for the selection
- evaluated exclusion criteria
- unresolved conflicts
- alternatives, if applicable

If several solutions are equivalent, list the alternatives as well.
For planning tasks, the reasoning behind the decision is especially important.
Instead of receiving only:
Examiner: Miller
it is much more useful to get something like:
Miller was selected because he is available,
has the required subject-matter qualification,
and currently has a lower examination workload
than the other eligible examiners, Smith and Wilson.
This turns a simple AI-generated result into a decision that can be reviewed and understood.
A Practical Project Structure
For a project like this, I would initially start with four Markdown files:
CLAUDE.md
docs/scheduling.md
docs/examiner-selection.md
docs/data-model.md
Their responsibilities are clearly separated.
CLAUDE.md- Defines the goal, workflow, priorities, and output format.
scheduling.md- Contains all rules for determining suitable examination dates.
examiner-selection.md- Contains eligibility requirements, exclusion criteria, and examiner-selection priorities.
data-model.md- Describes the structure and meaning of the input data.
The actual data can then be stored separately:
data/
├── dates.csv
├── candidates.csv
├── examiners.csv
└── availability.csv
This creates a clear distinction between instructions, business logic, and data.
Starting Claude Code
If the project is stored in:
examination-scheduling/
Claude Code can simply be started from that directory:
cd examination-scheduling
claude
Claude can then use the project-specific context defined in CLAUDE.md and the files referenced from it.
The important point is that the basic rules no longer have to be explained again in every new conversation.
Conclusion
A good CLAUDE.md is less like one large prompt and more like a specification for working with Claude.
For complex tasks, I find the following separation particularly useful:
CLAUDE.md
    ↓
defines workflow and priorities

docs/*.md
    ↓
describes the business rules

data/*
    ↓
contains the current input data

output/*
    ↓
contains generated results
For tasks such as scheduling, resource allocation, or examiner assignment, this structure prevents rules, current data, and individual decisions from being mixed together.
There is another benefit as well: the rule set remains readable independently of Claude.
The Markdown files are therefore not only context for the AI. They also become documentation for the project’s underlying business logic.
Further Reading
The Claude Code documentation provides additional information about CLAUDE.md and project-specific instructions: